Why Patch Automation Needs Brakes, Not Just an Accelerator
Author: Gene Moody, Field CTO at Action1
Patch management has a speeding problem.
The pace at which software changes is increasing, while the time available to IT teams to evaluate those changes is not.
The count and frequency of updates are both increasing, with no clear sign of slowing down anytime soon. New vulnerabilities are disclosed every day. Vendors release fixes on their own schedules. Browsers, operating systems, applications, and infrastructure all produce updates that need attention.
Meanwhile, the teams responsible for analyzing and deploying them are often dealing with limited staff, competing priorities, increasingly complex environments, and policies from a simpler age.
The result is predictable: the backlog grows. And when it happens, organizations start making trade-offs out of necessity. Testing time gets compressed. Review gets skimmed or skipped. Updates that ideally would spend time in a controlled test environment move directly into production because waiting another week may leave a known exposure open for another week, and the risk is too great.
Sometimes there is a legitimate argument behind that decision. A failure you control is generally preferable to a failure induced by an attacker. But that does not mean the answer is to become reckless about deployment. Pressing times sometimes call for hasty decisions.
What you can control, however, is how those pressures affect the parts of the process that remain within your control.
So how do you do that? Make the process smarter.
Automation Is Not the Same as Acceleration
Automation can produce failure at least as quickly as success.
A common way to think about patch automation is simple: find the update, approve it, deploy it, and do it faster. While that solves one part of the problem, it introduces another, more complex one in the process. If automation allows an update to reach 10,000 endpoints faster, it also allows a bad update to reach 10,000 endpoints faster.
The problem, therefore, is not automation. Problems begin when you start treating speed as the primary measure of automation. Good patch automation needs an accelerator, but it also needs brakes.
Those brakes determine where an update goes, when it gets there, what happens before it moves farther, and when deployment should stop. Automation is only useful as long as it remains effective. Once effectiveness fails, it takes efficiency away, not creating it.
Start Small, Then Earn the Right to Go Wider
The traditional answer to patch testing has generally been a test lab. That is still useful, but no lab can reproduce every combination of hardware, software, configuration, and user behavior found across a production environment. And while everyone has a test environment, not everyone is fortunate enough to have one entirely independent of production systems.
Since we all contend with that to some degree, a better approach is to make controlled production deployment part of the validation process. This is where business context and intimate infrastructure knowledge are critical.
Think about the process you are automating. There is far more to it than sending a file and executing it. End to end, the process involves many decisions, along with knowledge and experience specific to your environment. That needs to be automated too, or you are simply accelerating execution, not processes.
Start small. Perhaps, with IT staff, a representative collection of endpoints, or systems that reflect some of the more complicated configurations in the environment.
Success starts with planning and ends with a desired outcome, so establish upfront what success looks like. What does an automation do, to what, and when? What is the desired outcome? And where are the brakes if it deviates from the path to success?
Did the update apply successfully? Did endpoints remain healthy? Did applications continue functioning? Did failure rates stay within an acceptable threshold? Only after those conditions are met should the update move to a larger group.
This is the fundamental idea behind staged deployment, or update rings. Instead of making one binary decision — deploy everywhere or don't deploy — the organization creates a progression of increasingly larger groups.
The important part is that this progression should not have to depend on someone's judgment every time. It can be governed by predefined criteria for when to proceed and when to stop because conditions no longer meet the expected baseline.
That is where automation becomes considerably more useful. Automate every decision you can define. If it requires human judgment, keep it. But anything you do the same way more than twice is just wasted time.
The Goal Is Not Zero Human Involvement
There is a temptation to describe fully autonomous patching as the ultimate solution. I personally don't think it is.
There are times when automation makes perfect sense. There are also systems where a human should remain in the loop. Automation is part of the solution — a significant one — but seldom the whole solution.
A domain controller, production database, ERP system, or other business-critical workload may deserve different treatment from a standard employee workstation.
Fortunately, larger environments tend to become more concentrated, so as you scale, you typically gain more liberty to designate some systems as less mission-critical. Like canaries in a coal mine.
The objective is not to eliminate human judgment so much as to use it where it matters. That means no longer spending human judgment on decisions that can safely be automated, while preserving it for decisions where the consequences justify the added attention.
If the system can evaluate deployment results, stop an update that is failing, and continue a proven update automatically, the administrator is managing the policy and process rather than manually driving every deployment.
The Efficiency Dividend
The largest single benefit of this approach is time. Instead of manually repeating the same steps, administrators can establish groups and success criteria once, then let the deployment process handle routine progression.
The goal is not to eliminate oversight, but to reduce unnecessary intervention. And that changes what automation means.
Modern patch management platforms can support this model by combining staged deployment with clear controls over when updates progress and when they stop.
Action1, for example, provides Update Rings for sequential endpoint deployment, with criteria that determine whether an update moves forward or stops.
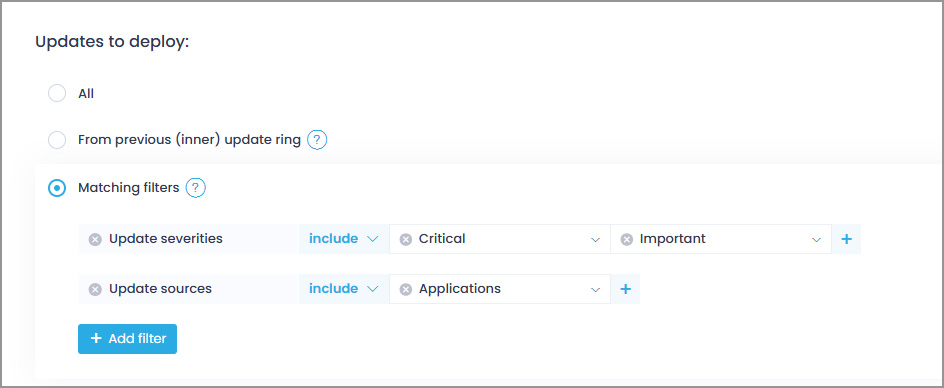
It also supports manual approval workflows and endpoint groups that can be organized around different characteristics and deployment requirements.
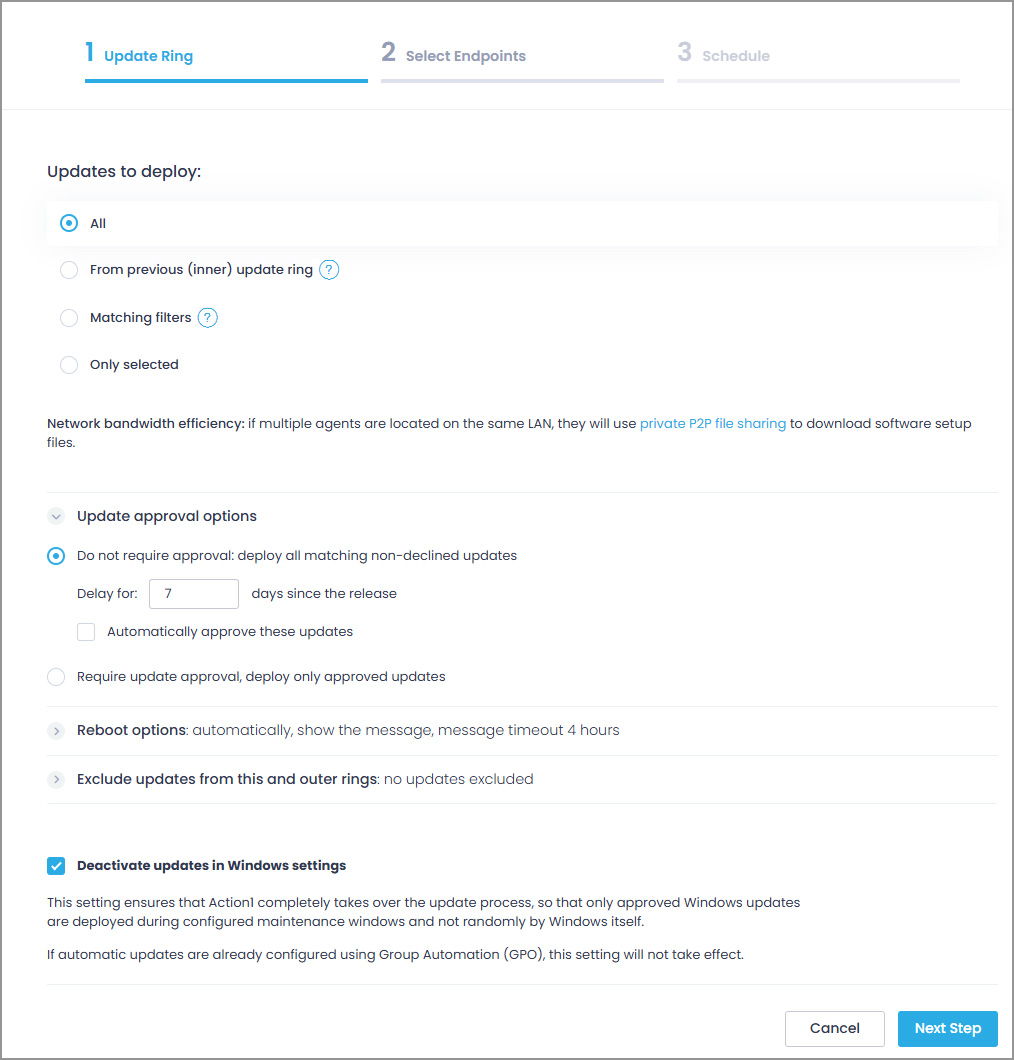
The value of those capabilities is not simply that they make patching faster. They make faster patching safer.
The goal should not be to test everything perfectly before deploying anything; most organizations cannot sustain that model. Nor should it be to deploy everything immediately and hope nothing breaks. The practical answer is controlled automation: make it work consistently, then work to make it faster.
Test where testing provides value. Start small. Define success. Let proven updates progress and stop problematic ones. Treat business-critical systems differently when necessary, and keep humans involved where the consequences justify it. Then automate everything else.
Make patch automation safer with Action1 by combining Update Rings, predefined deployment criteria, and manual approvals where needed.
Start with 200 endpoints free forever and scale when you're ready.
The payoff is a patching process that can keep pace with the environment without requiring the IT team to run faster every month.
Sponsored and written by Action1.
What's Your Reaction?
 Like
0
 Dislike
0
 Love
0
 Funny
0
 Wow
0
 Sad
0
 Angry
0




Comments (0)